Seedance 2.5 Fashion Ad Prompt: Suede Boots, Red Sand and Liquid Gold
One Seedance 2.5 footwear test: red dunes, suede detail and liquid-gold ripples. See the original film, settings, scene deviations and limits.
PROMPT LIBRARY · FASHION · SURREAL FOOTWEAR
By Token360 · Test date: November 5, 2026
Tested once · text-only · concept film
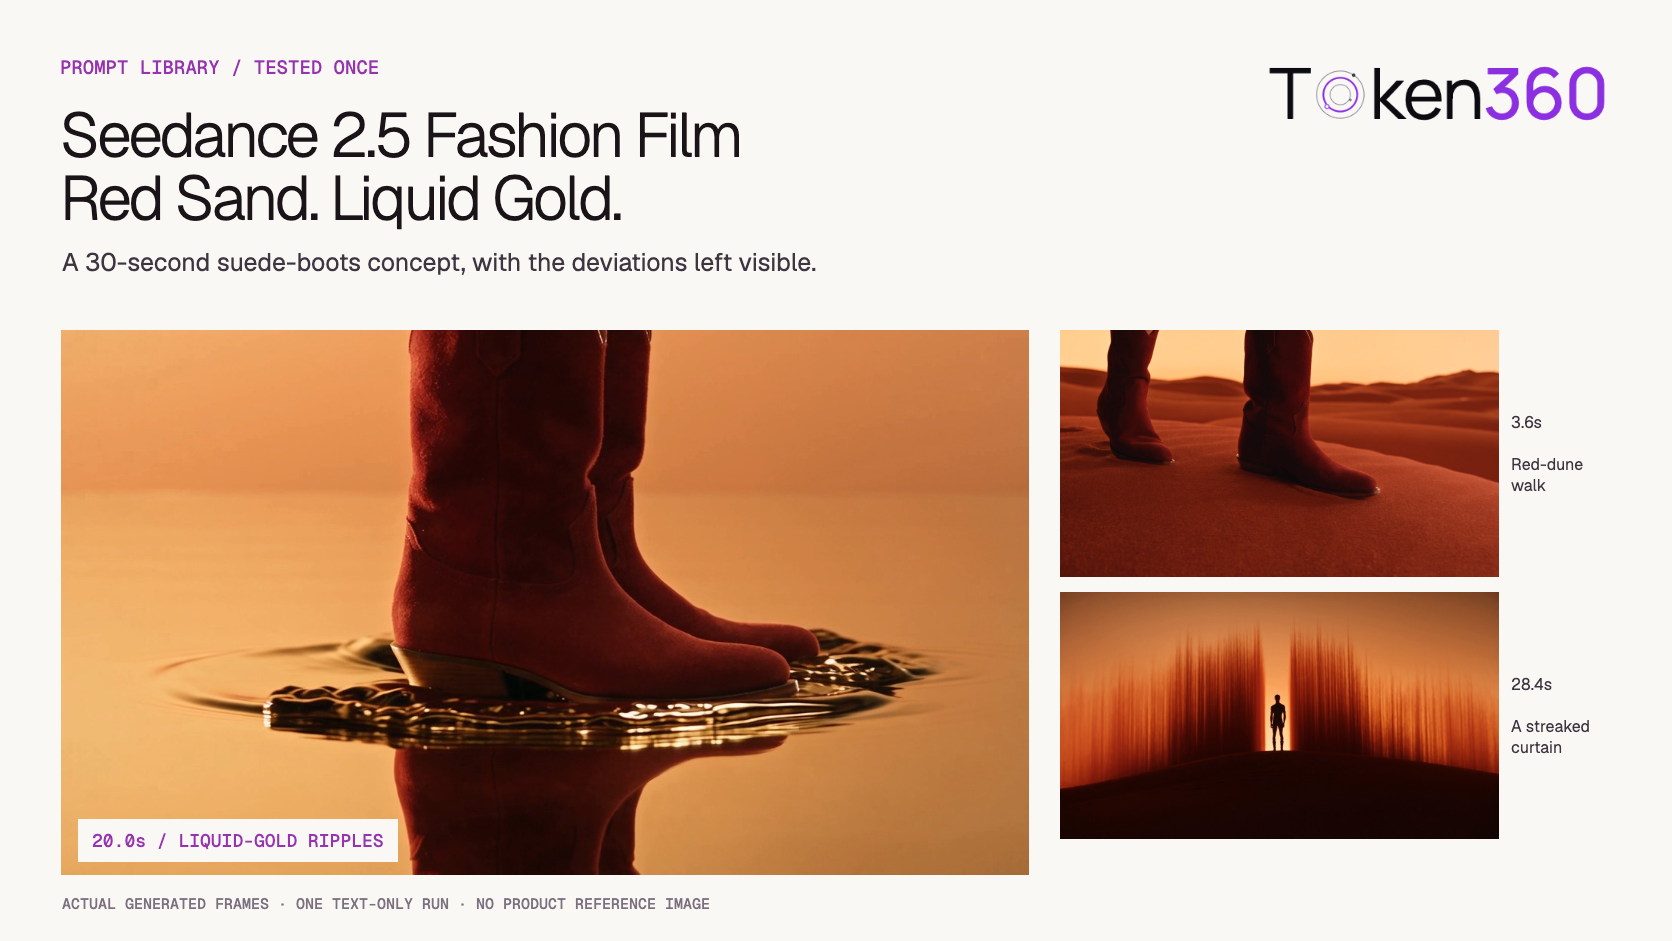
This Seedance 2.5 fashion ad prompt produced a thirty-second sequence of red dunes, suede boots, floating figures and liquid-gold ripples in one Token360 API run. The main visual ideas appeared, but falling became gentle suspension, rapid cuts became long dissolves, and the final sand curtain looked more like vertical strands.
The result is useful as a concept-film reference, not evidence of a repeatable advertising template or an accurate reproduction of a real product. There was one generation, no reference image and no external edit. This page shows that original output rather than selecting a winner from several attempts.
Read first: planning an AI product-film shot list explains how to separate visual beats. This page examines one specific surreal footwear prompt and its single output.
What did the suede-boots concept film produce?
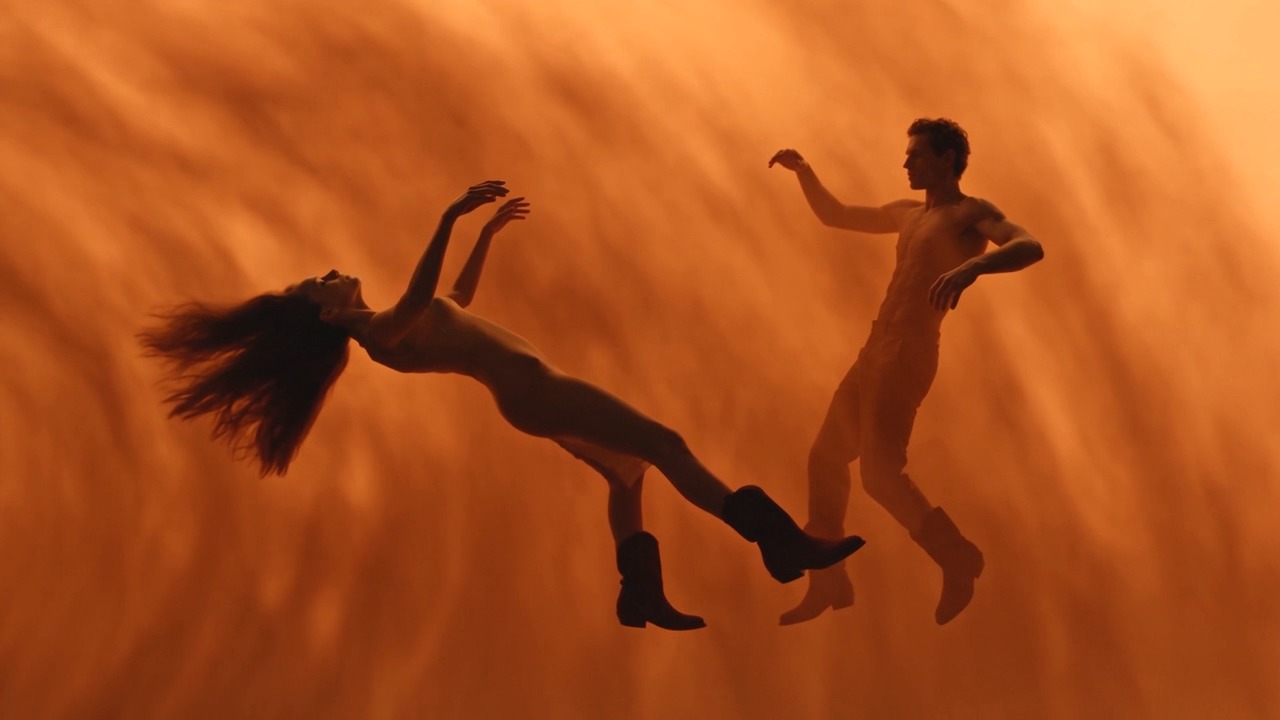
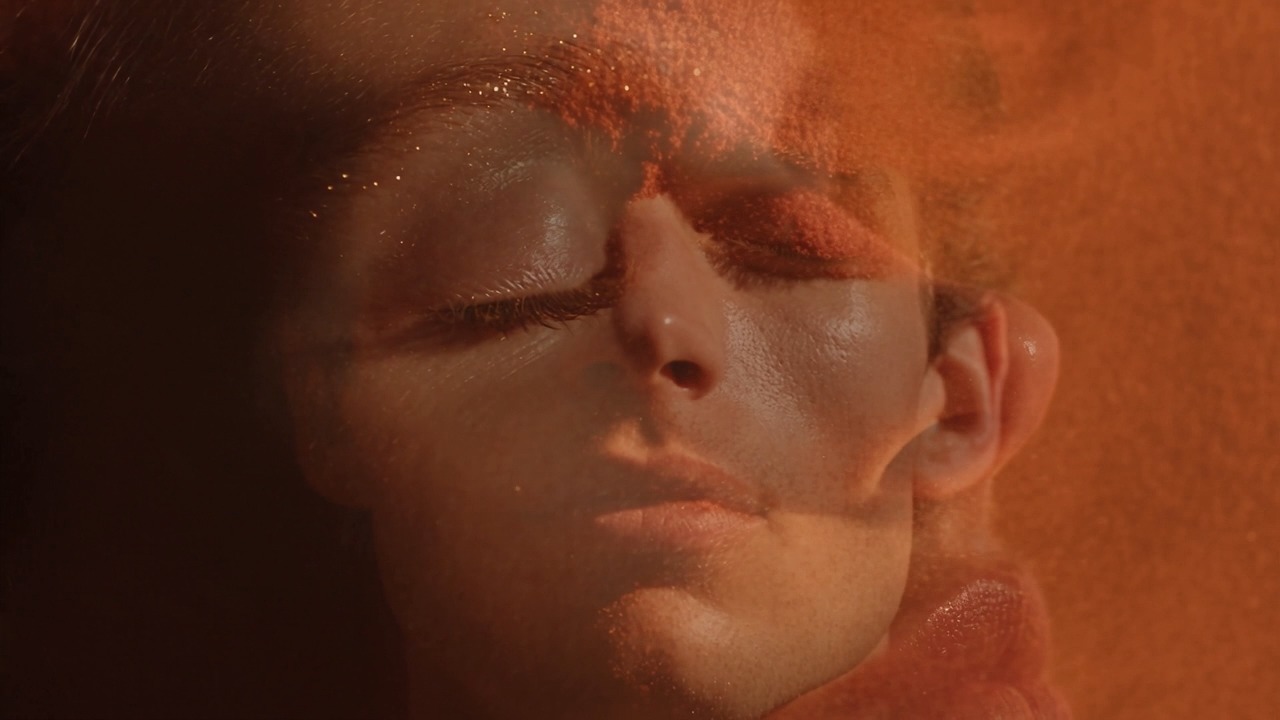
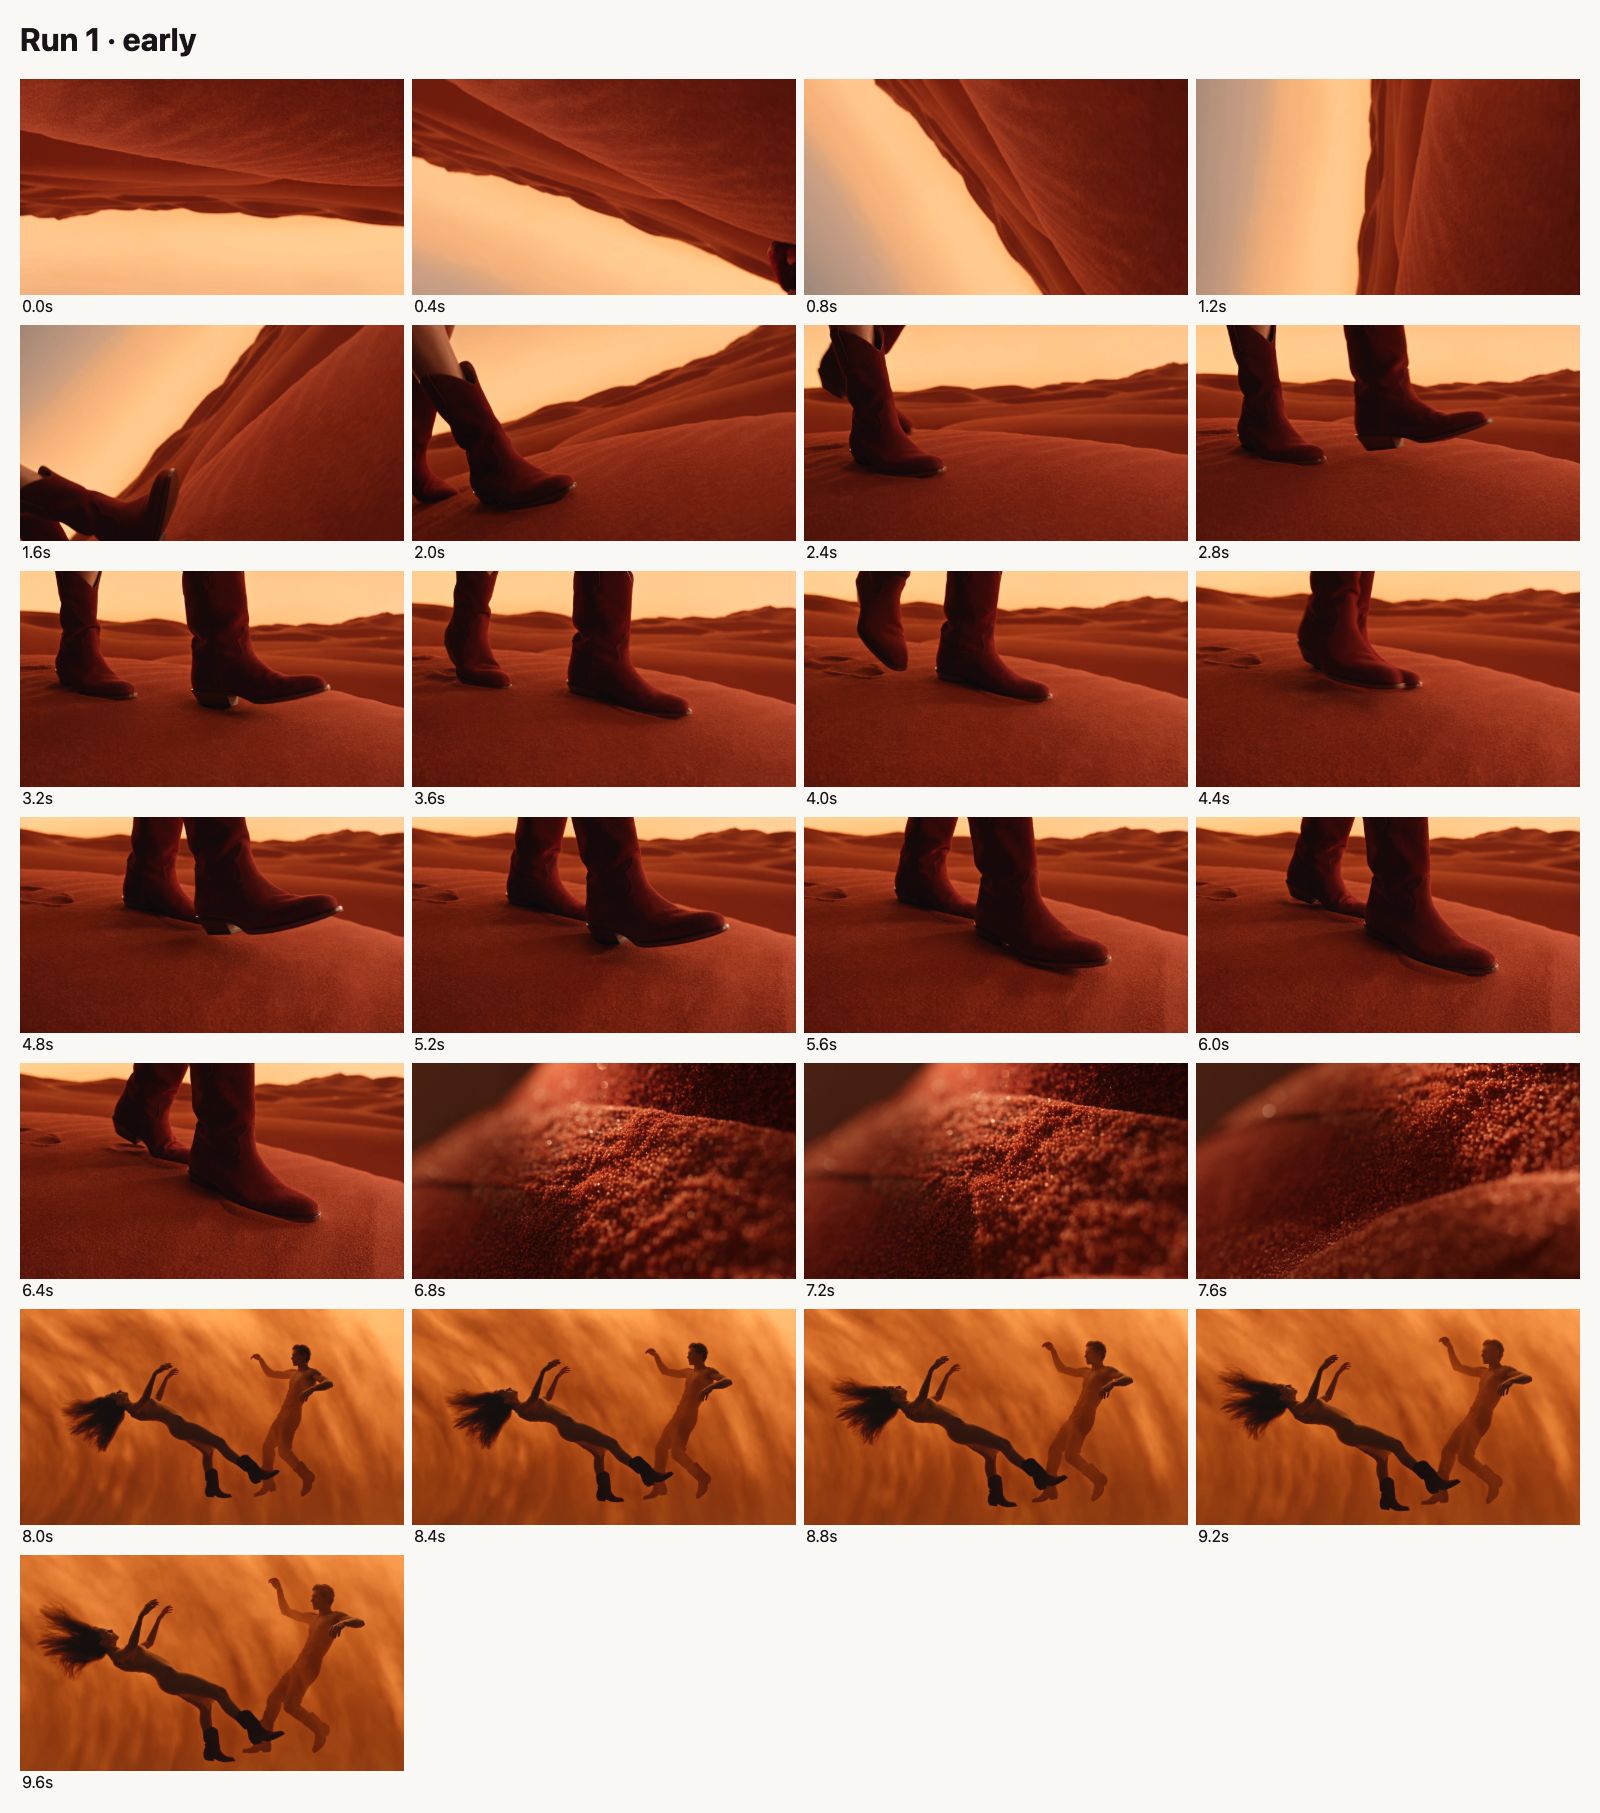
The output forms a recognizable red-and-amber sequence: an inverted desert opening, boots walking, material detail, floating people, face close-ups, gold-like ripples and a silhouette ending. Those scenes provide a concrete style reference. They do not establish exact execution of the requested movement, lighting, transitions or product details.
Run 1 · original generation · requested 30 seconds, 720p, 16:9, audio disabled. No externally assembled shots and no selection from repeated generations.
The prompt intentionally asks for impossible imagery, including weightlessness and liquid gold. Those effects are not automatically defects. The useful comparison is whether the film delivers the requested version of the fantasy while keeping the bodies, boots and sequence readable.
For example, floating bodies satisfy a broad weightless mood, but not necessarily the specified backward fall. Gold spreading around boots conveys the visual motif, but not necessarily multiple footsteps turning into gold. A compelling image and a correctly executed action are related but different acceptance questions.
Which model and settings were used?
The recorded Token360 request names seedance-2.5, with a thirty-second duration, 720p, 16:9 and audio generation disabled. It contains no seed or fps field. The actual file has a video track of approximately 30.04 seconds at 1280 × 720 and 24 fps, with no audio track.
Text-to-video; no product or person reference image
Generation count reviewed
One
Seed / fps request fields
Not sent
Measured output
30.0417-second video track; 721 video samples; average 24 fps
Dimensions / audio
1280 × 720; no audio track
Test date
November 5, 2026
The measured 24 fps is an output property, not a setting we supplied. Likewise, the “30-second” wording in the prompt was accompanied by an explicit duration field. The source review reports that the model schema consulted for this run did not list seed or fps; this page does not infer that those fields are universally unavailable.
For a new request, use Token360’s selected-model capability guidance to check the current schema. Settings from an earlier Veo example should not be assumed to work on this model. The parameter record describes this test, not every provider’s endpoint or a permanent model specification.
Which scenes appeared, and where did the output diverge?
The sampled sequence contains the main visual stages, but the closest matches are at the level of setting and motif. Motion amplitude, edit rhythm and the final particle effect differ from the brief. The timeline below distinguishes a scene appearing from all of its requested details being verified.
Approximate segment
Observed output
Difference or limit
0–6.4s
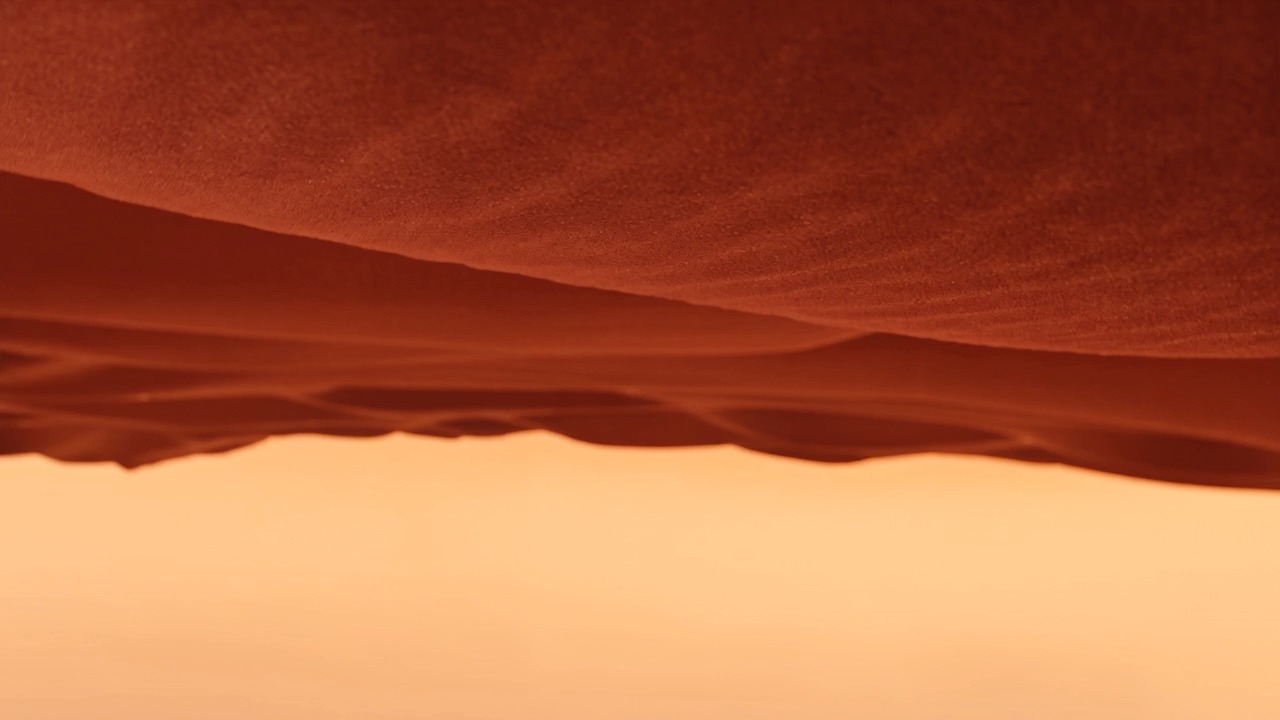
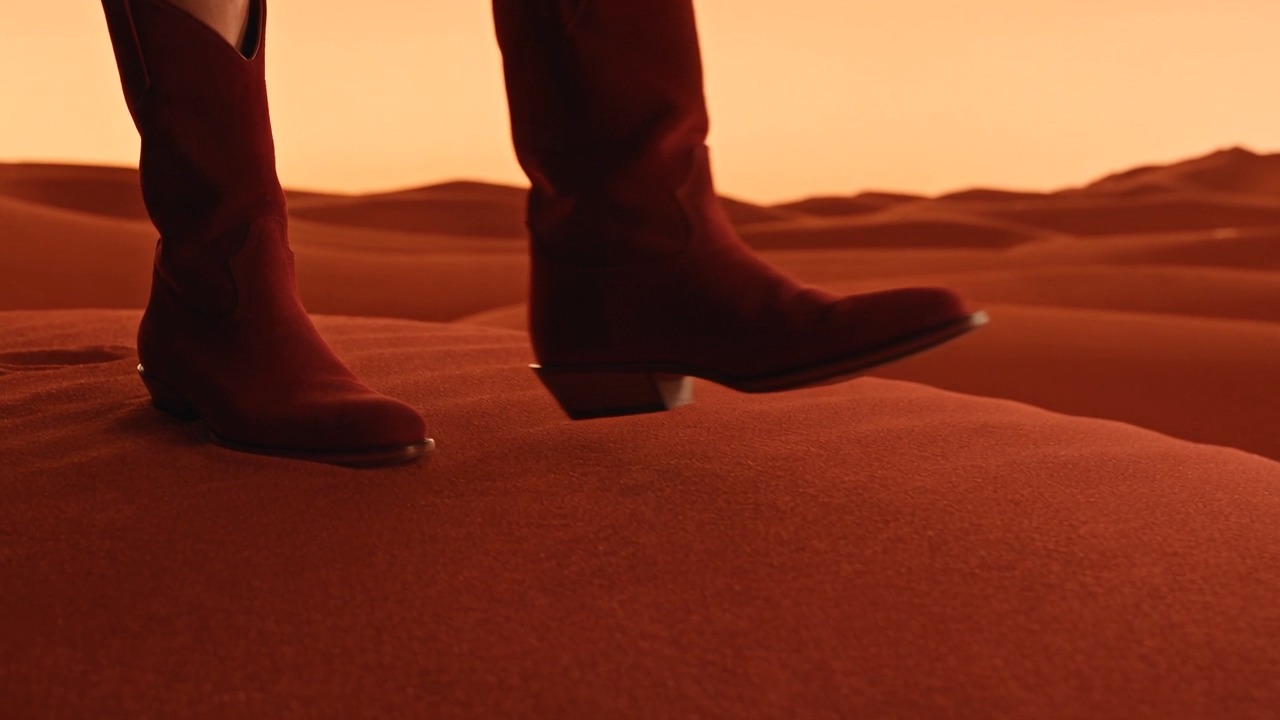
Inverted dunes rotate toward a boots-walking view.
Readable steps do not certify every seam, sole detail or contact frame.
6.8–7.6s
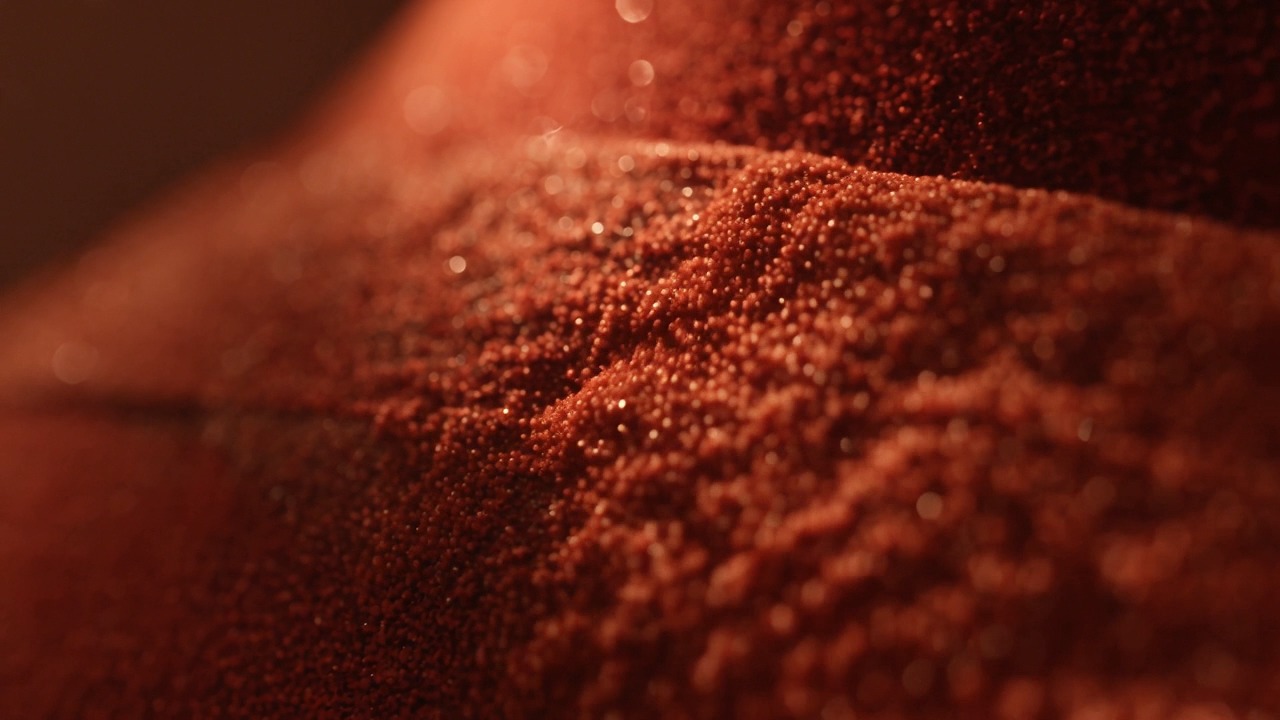
Extreme close-up of granular red surface detail.
The isolated macro cannot establish the same product surface across shots.
8–10s
Two figures in backward-leaning, suspended poses.
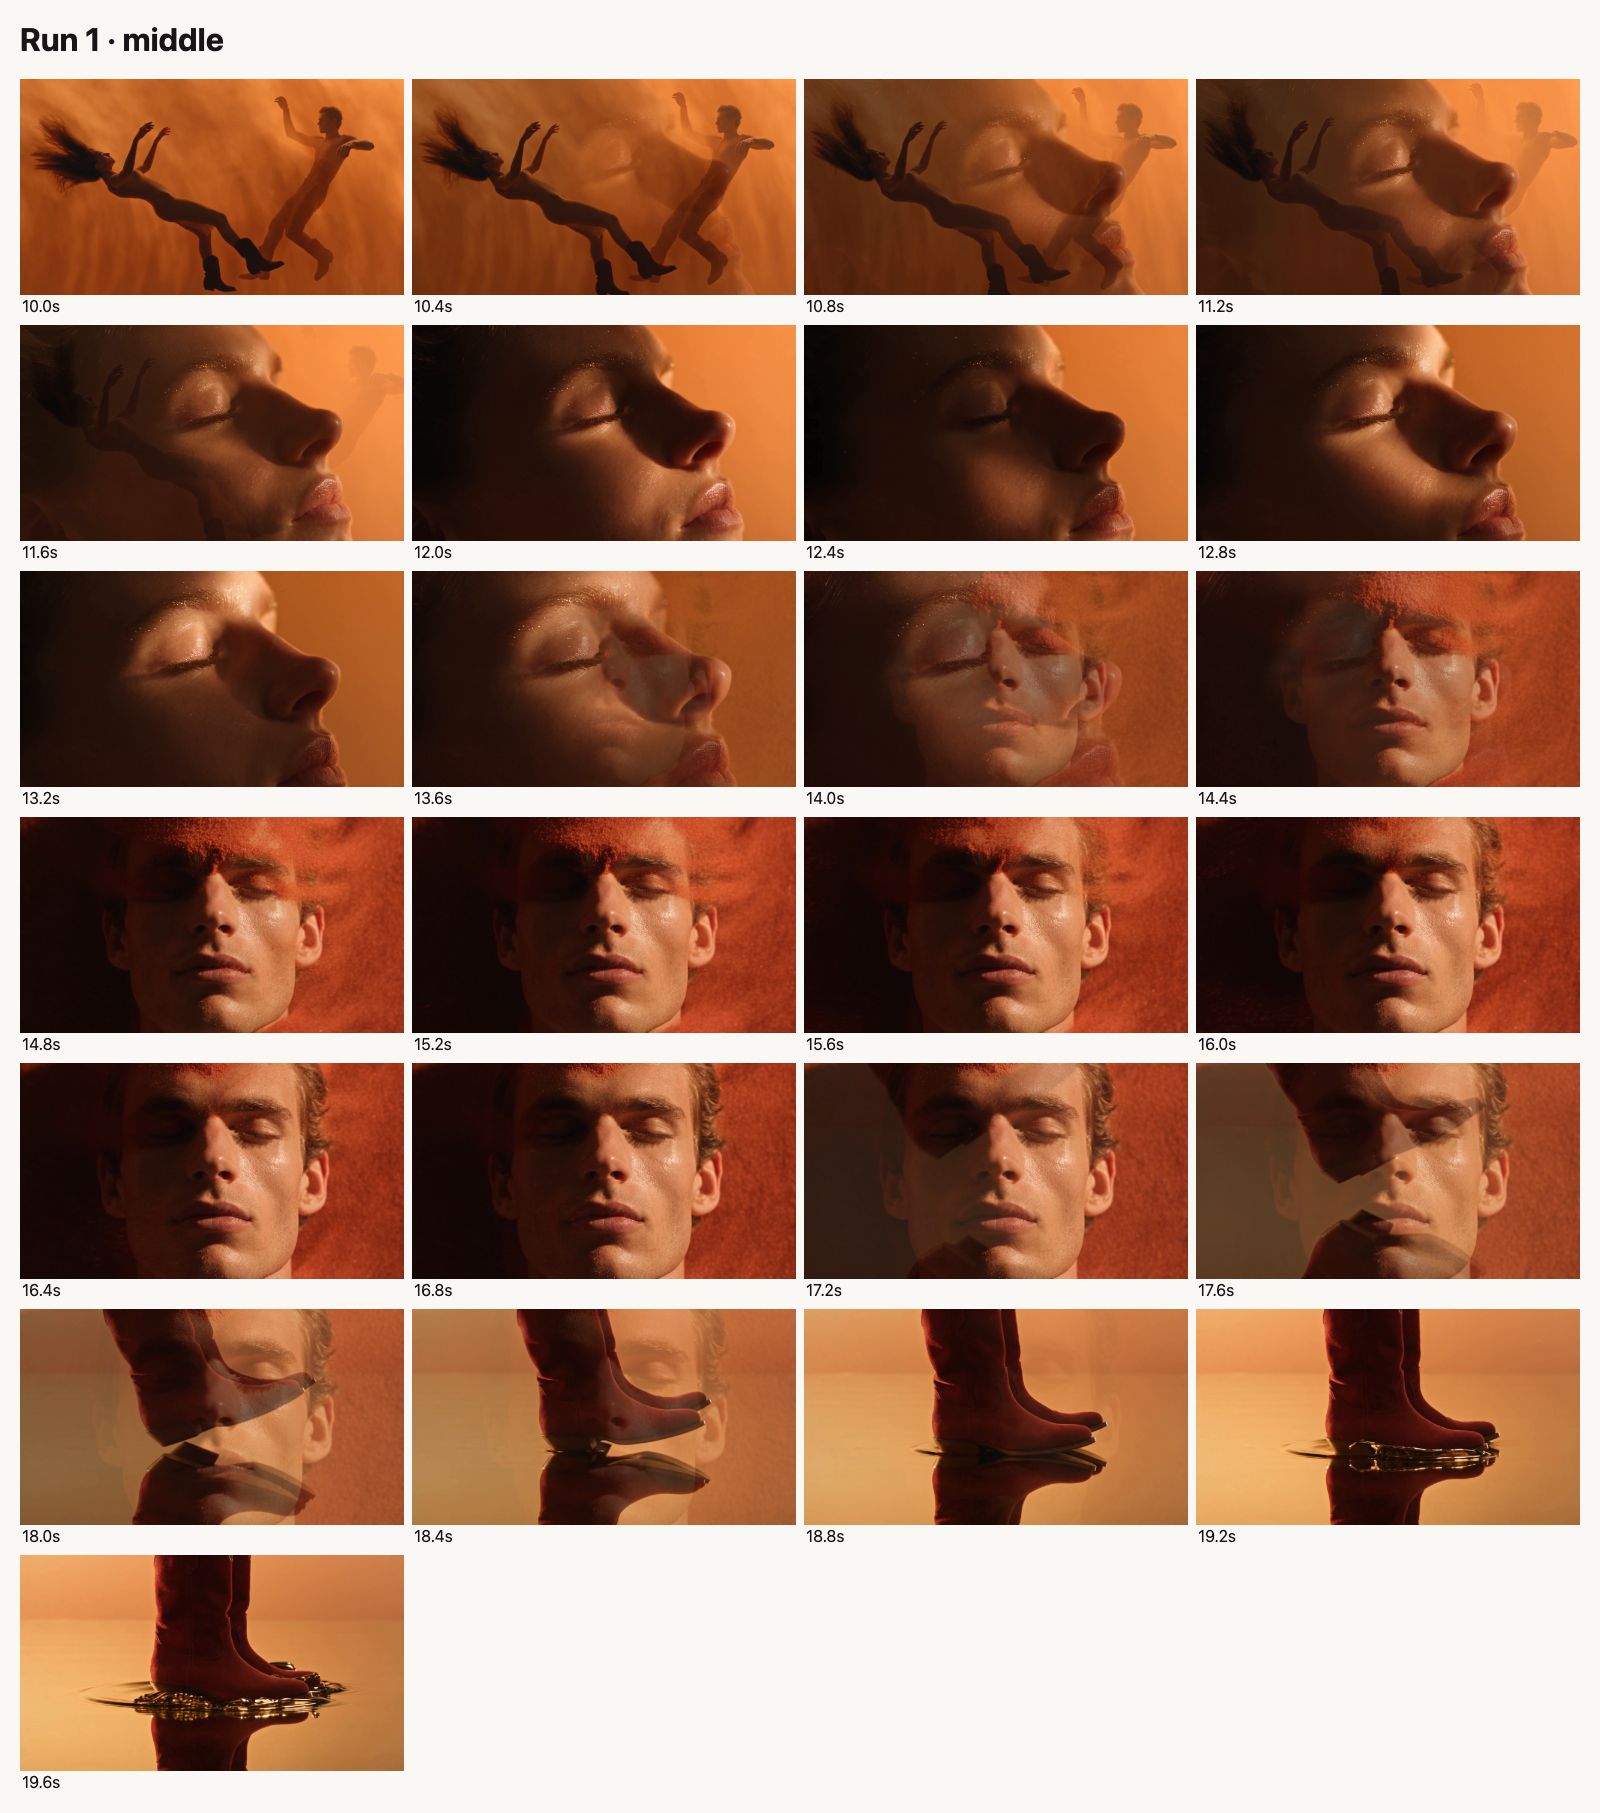
Closer to slow floating than a clearly developed backward fall.
About 10–18s
Warm face close-ups with visible particles.
Extended dissolves replace the requested rapid cuts; cold rim light is not prominent.
About 18–23s
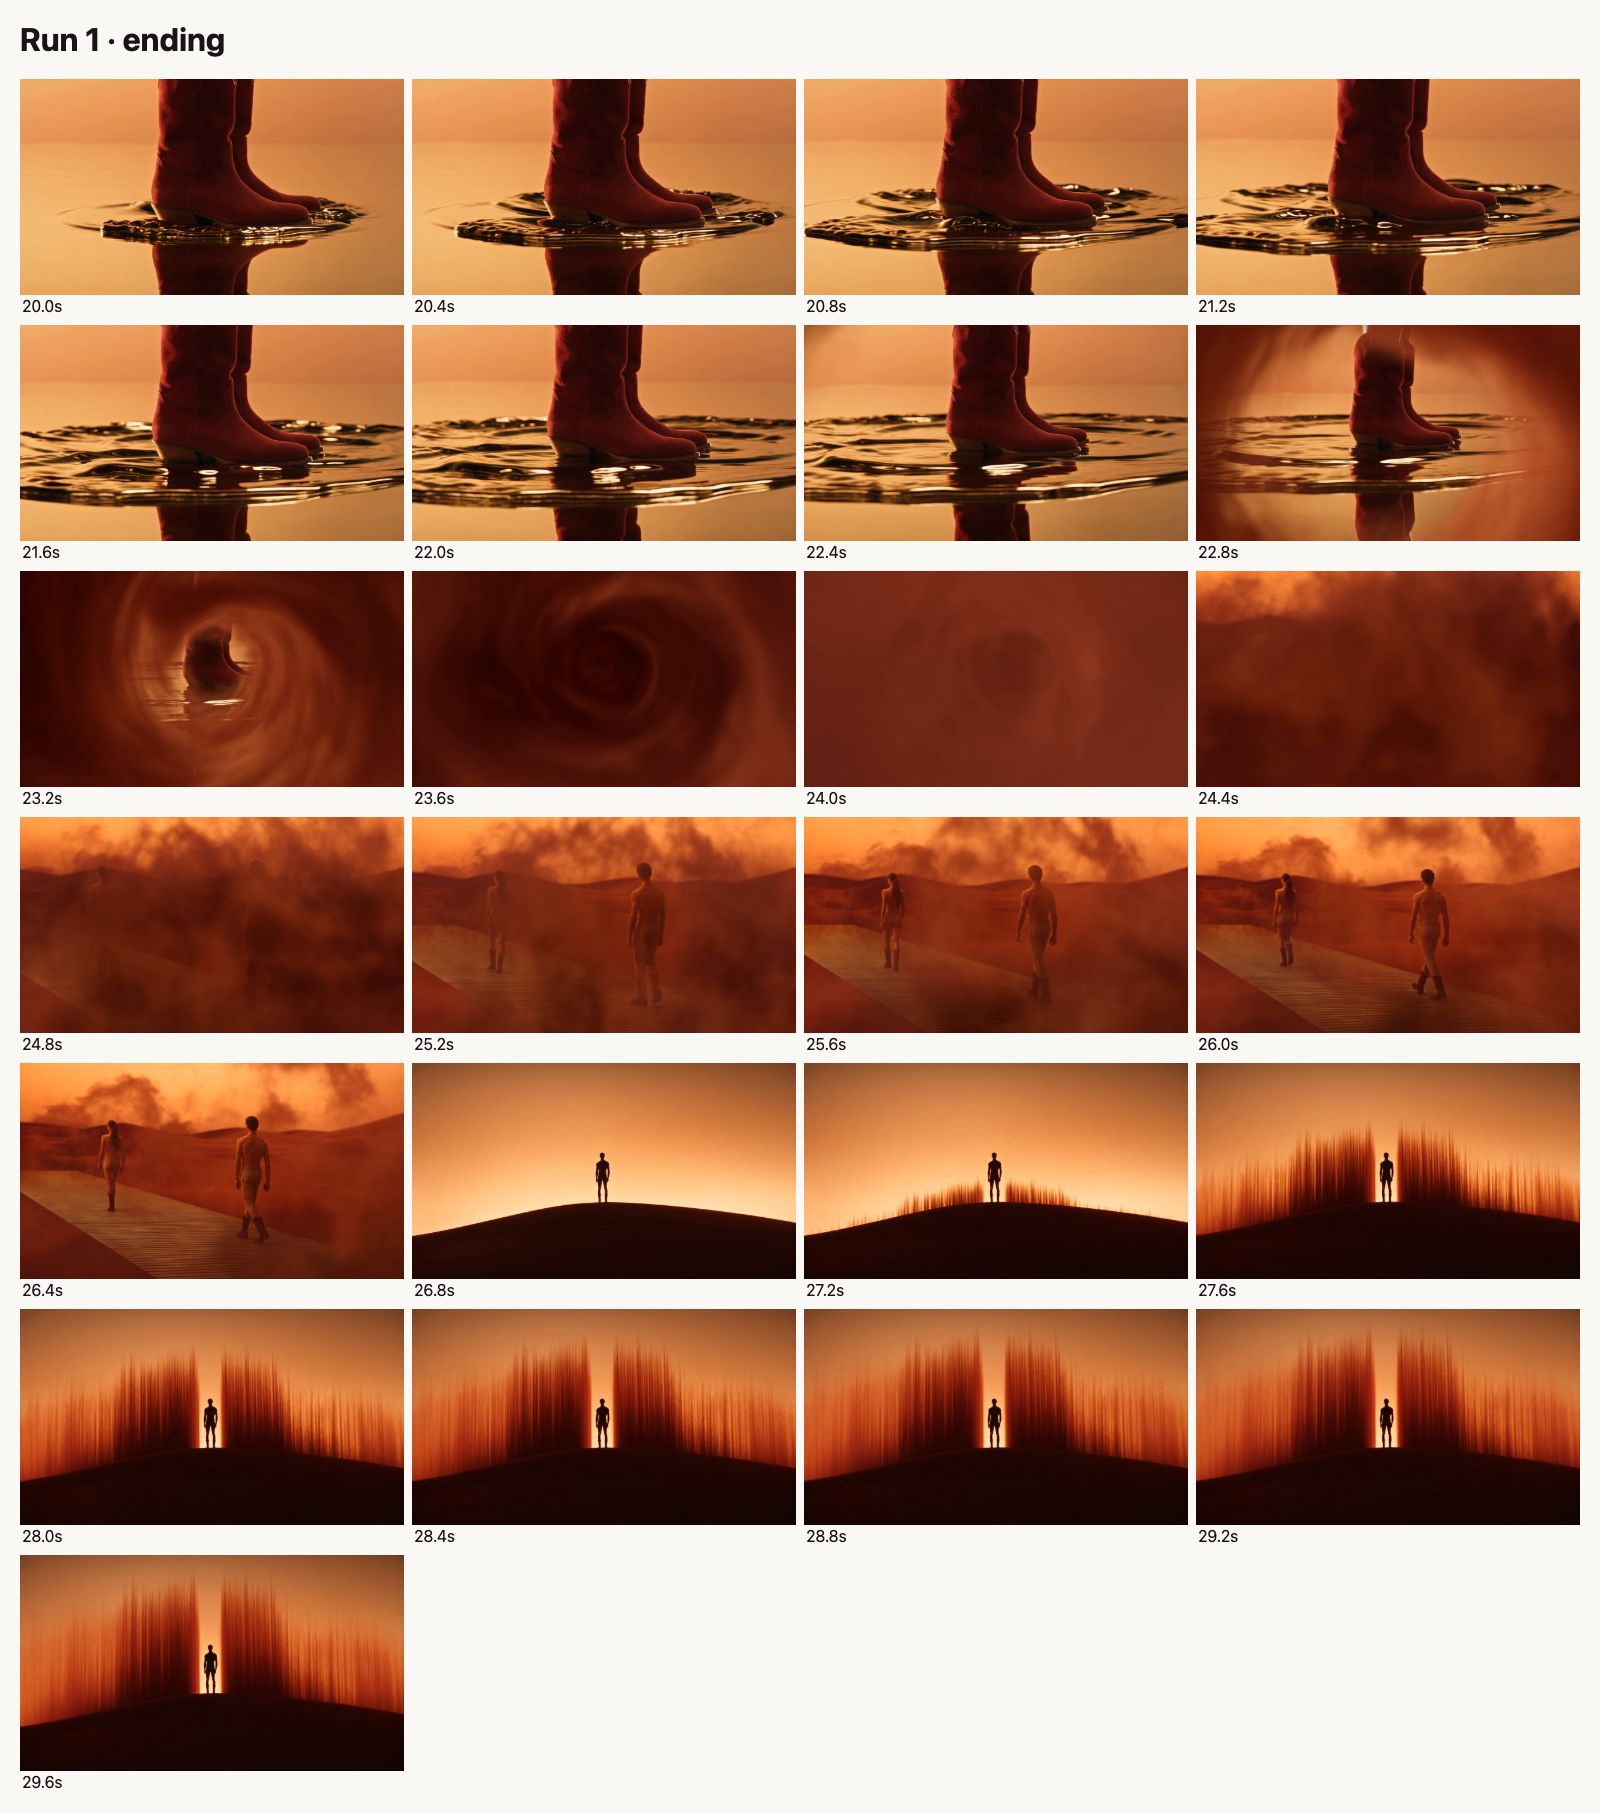
Boots descend toward a reflective surface and gold-like ripples expand.
Not a full walking sequence in which successive steps become gold.
About 24–30s
Dust transition, desert runway and lone silhouette ending.
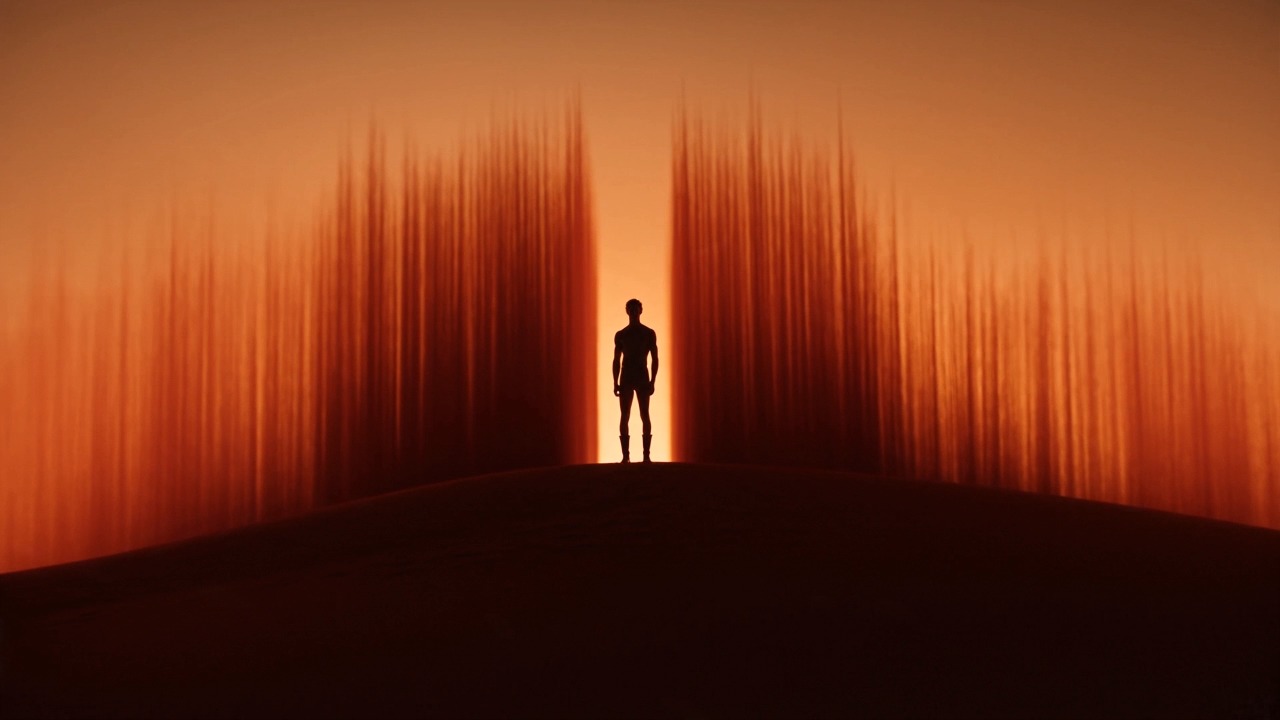
The raised curtain reads as vertical filaments or streaks, with weaker granular sand detail.
The opening preserves the idea, not a verified product identity
The opening samples progress from an upside-down landscape through a rotation into a low boots view. Later frames show lifted and planted feet in a readable order. This supports the presence of walking in the concept sequence; it does not establish flawless gait or precise identity of the boot design across every frame.
0.0s
2.8s
6.8s
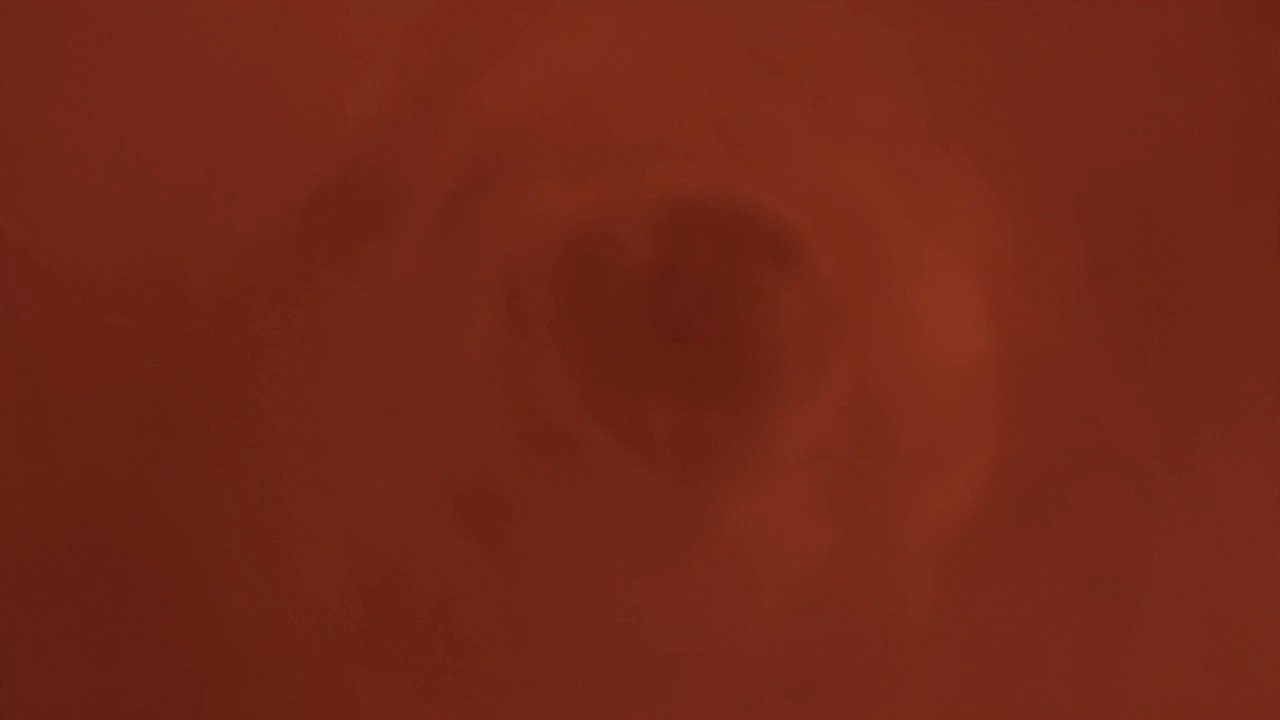
Inverted opening, a lifted boot at 2.8s, and granular macro detail at 6.8s. Actual generated frames. Times identify sampling targets, not frame-exact cut boundaries.
The material insert is attractive because red grains and surface texture fill the image. Its extreme scale also removes much of the shape information that would connect it unambiguously to a specific boot. Without a reference product, we cannot use that texture shot to certify the correct nap, stitching or construction of a real item.
Weightlessness and rapid editing are separate requirements
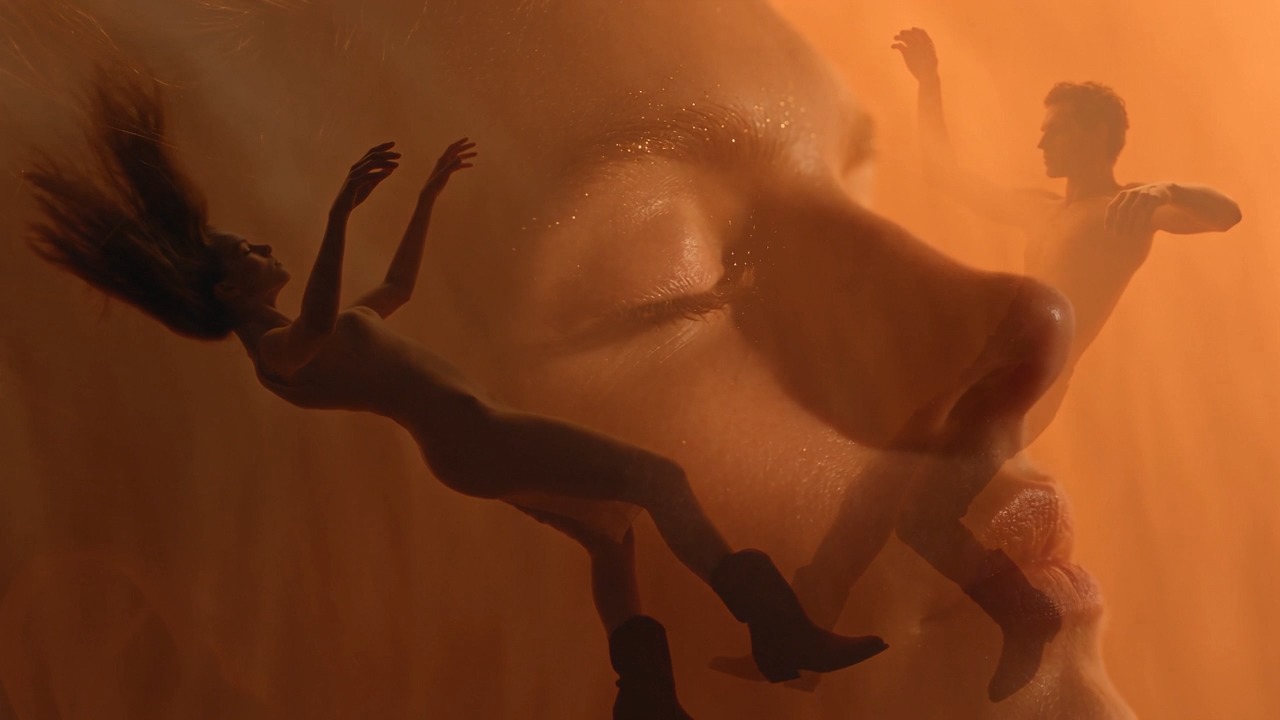
At around 8–10 seconds the figures remain suspended in differing backward-leaning poses. The scene communicates the intended surreal atmosphere, while the degree of falling is less apparent than the brief asks for. It is reasonable to describe this as a reinterpretation of the motion rather than claiming the requested fall was fully executed.
8.0s
10.8s
14.0s
Suspended figures at 8s; layered imagery during the dissolves at 10.8s and 14s. Actual generated frames. Times identify sampling targets, not frame-exact cut boundaries.
The face sequence gives another specific comparison. Multiple samples show overlapping outgoing and incoming images, supporting the observation of long dissolves. That rhythm differs from rapid cuts even if the lighting and faces remain visually polished. Warm orange tones dominate; the requested colder edge light is not a strong feature of the reviewed samples.
Liquid gold appears, but successive transformed footsteps do not
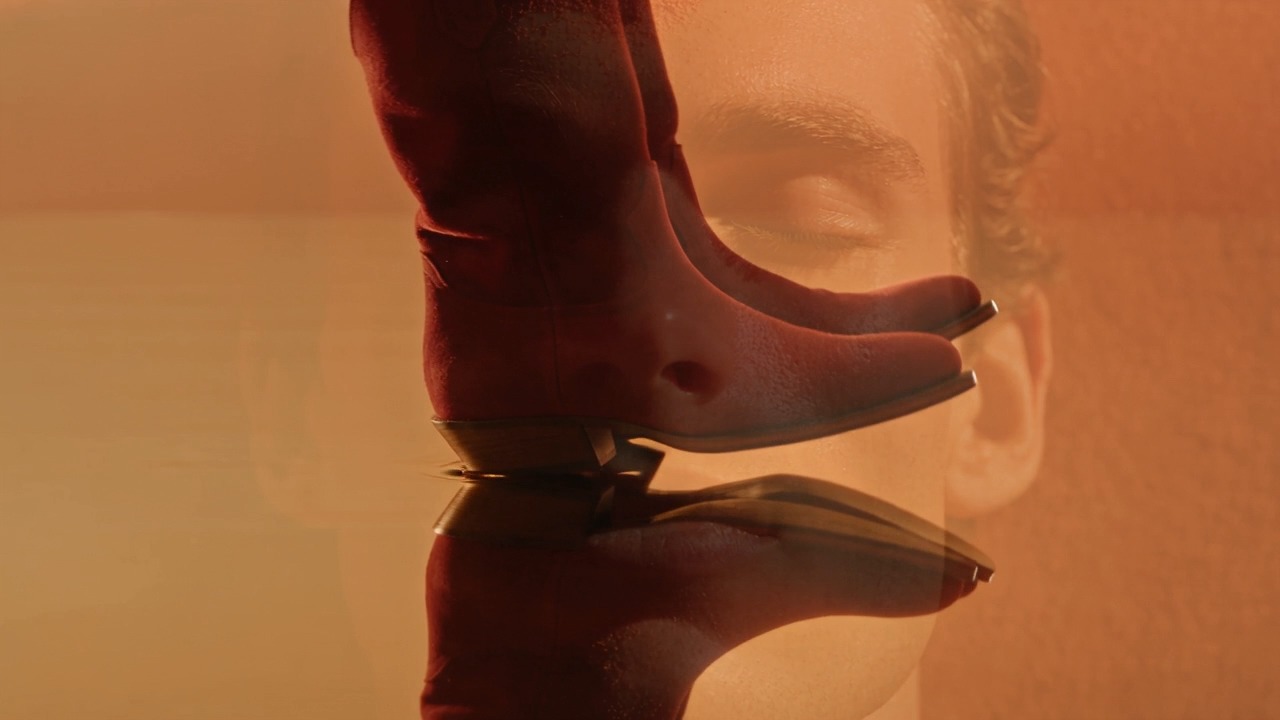
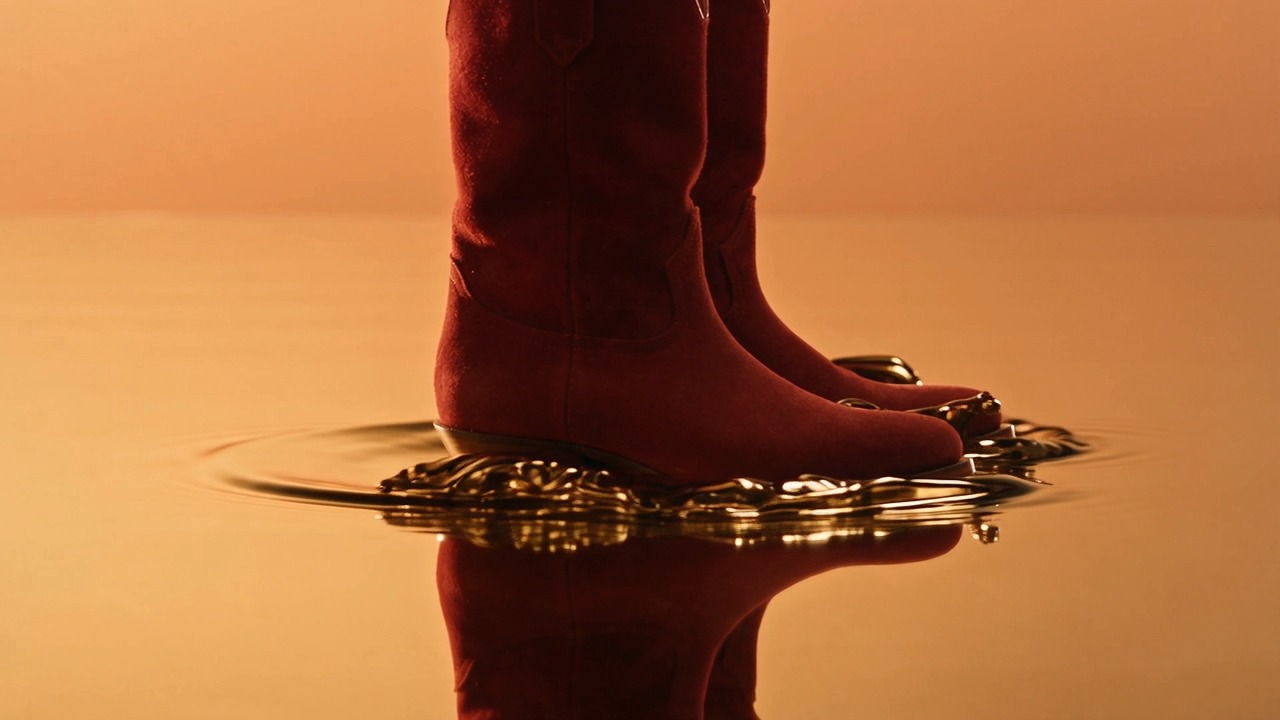
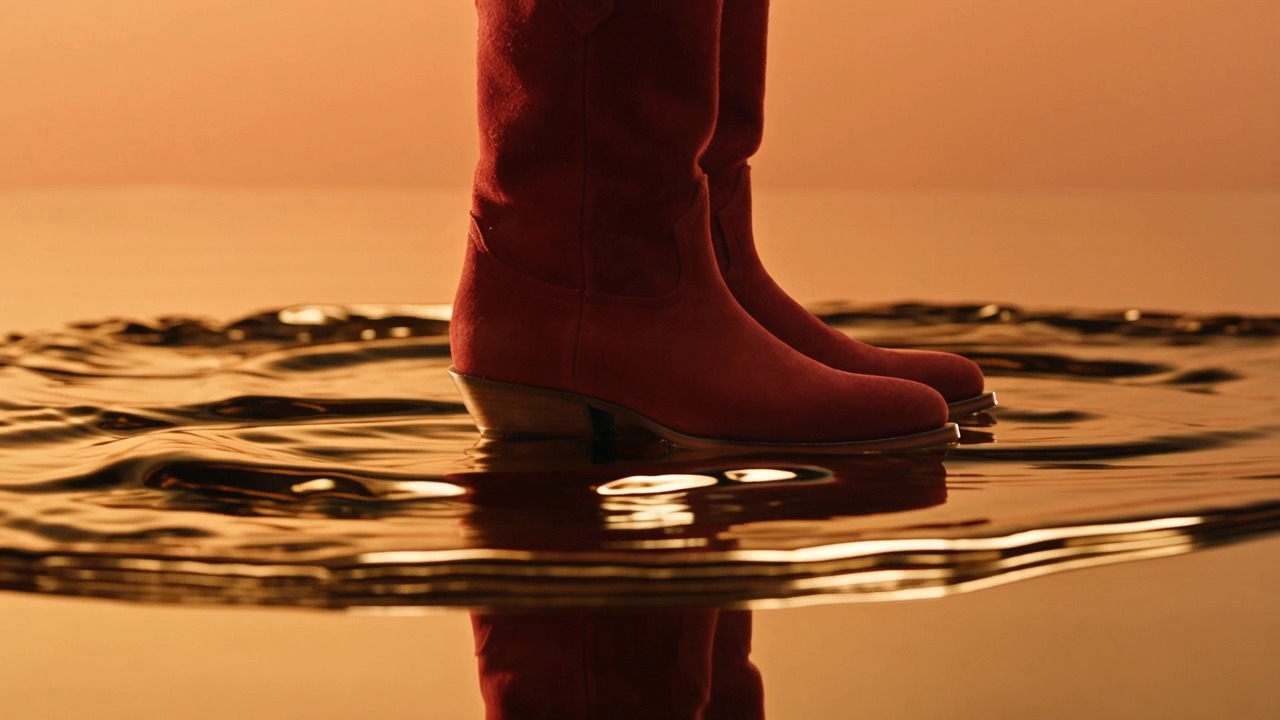
The middle-late sequence shows boots approaching the mirror-like surface and a gold-like ring spreading around them. It supplies the liquid-gold motif. The visible action is closer to a landing followed by expanding ripples than a continuing walk with a transformation on each step.
18.4s
19.6s
22.0s
The boots approach the reflective surface at 18.4s, then gold-like ripples spread at 19.6s and 22s. Actual generated frames. Times identify sampling targets, not frame-exact cut boundaries.
This distinction matters if a creative brief depends on a repeated cause-and-effect action. A single landing and a trail of transforming footsteps can suggest different stories. The test provides evidence for the former visual reading, not a reason to silently mark the latter requirement complete.
The closing silhouette works as a motif; the curtain changes material
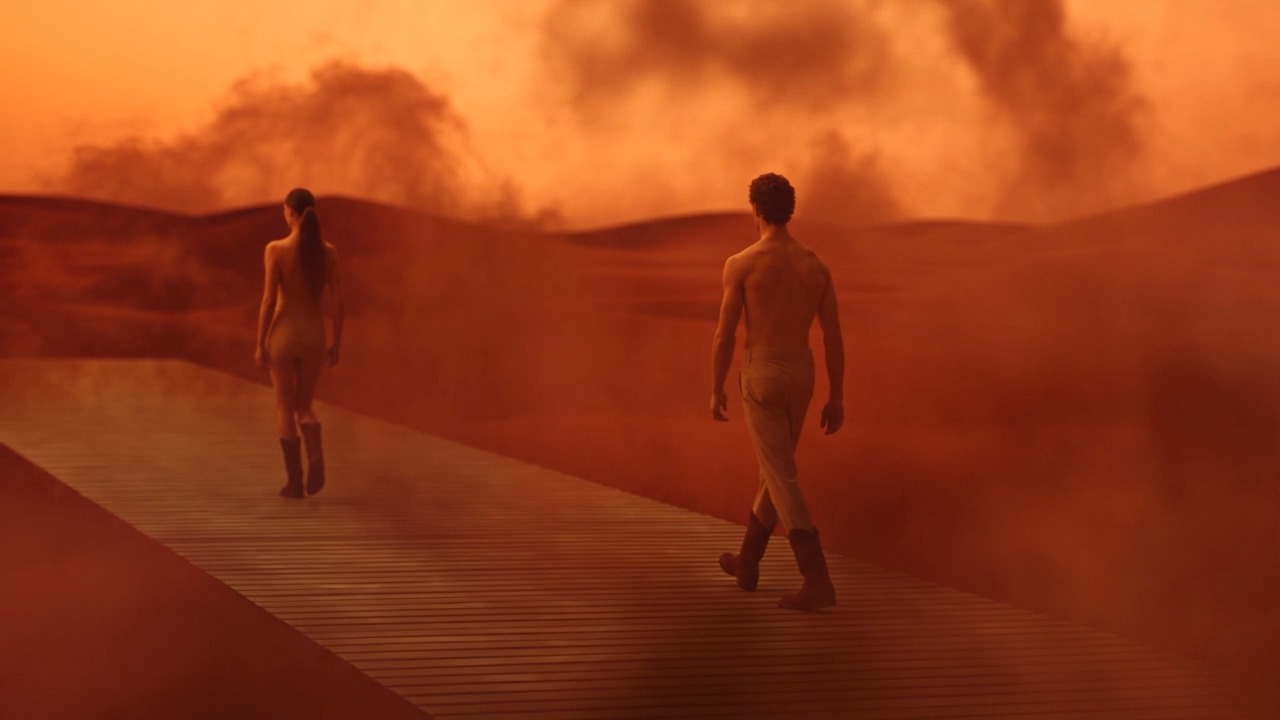
The ending moves through red dust into a runway-like scene, then a lone figure against the sunset. Behind that figure, the raised formation has a strongly vertical, streaked appearance. It resembles strands more than a visibly granular sand curtain, so the silhouette idea is present while the material treatment diverges.
24.0s
26.0s
28.4s
Red-dust transition at 24s, runway view at 26s, and the vertically streaked curtain at 28.4s. Actual generated frames. Times identify sampling targets, not frame-exact cut boundaries.
How much of the video was checked?
This Blog 144 review inspected file metadata and 75 images sampled at 0.4-second intervals from 0.0 through 29.6 seconds. That is denser than the initial broad inspection, but still not an exhaustive frame-by-frame motion review. Brief intersections, tiny shape changes and exact cut boundaries can fall between samples.
The supplied earlier review used an approximately 1.9-second overview and denser 0.4-second checks in selected passages. This edition extended the 0.4-second sample grid across the clip. No obvious extra feet or broken boot bodies were identified in these samples; that narrow observation must not be expanded into a “flawless throughout” claim.
This separates the file checks described in video output validation from creative acceptance. A valid thirty-second file can still reinterpret the actions and edit rhythm requested by a script.
What was the tested prompt?
The submitted text describes a surreal sequence rather than an ordinary product demonstration: inverted red dunes, suede detail, floating figures, gold-like liquid and a sunset curtain. The source text was preserved in the test records. Authorization to republish it in full remains unresolved.
The full prompt is omitted from this publication export while source permission is unresolved. The stage summary and review describe what was tested.
The test did not rewrite the supplied wording. The concepts in the paragraph above are a summary, not a newly tested replacement prompt. Removing the full text for publication would not turn that summary into a proven generation recipe.
How should a creative team use this reference?
Use the output to judge whether this red-sand and liquid-gold direction suits a visual proposal. Evaluate concept coverage, action readability and product structure separately. A stylized film may legitimately bend gravity and material behavior, but that does not make every unintended limb, shoe-shape or transition change acceptable.
Define the intended use. A mood or style proposal asks a different question from a product film that must reproduce a client’s exact footwear.
Keep the recorded conditions visible. This result is text-only, thirty seconds, 720p and silent. A different duration, reference input or audio setting becomes a new condition.
Check contacts and silhouettes. Review the feet during walking, limbs during suspension and boot shape before and after the liquid effect.
Evaluate rhythm explicitly. Decide whether the slower dissolves fit the proposal. Do not mark a rapid-cut requirement as satisfied simply because the sequence looks cinematic.
Validate a real product separately. This unbranded, reference-free test cannot establish accurate packaging, logos, seams or sole geometry for a specific item.
If a shorter edit is required, choosing AI video clip duration provides the broader planning context. This test does not show that the same sequence survives compression into six or eight seconds. No revised duration or corrective prompt was generated for this review.
Is this a stable fashion-ad template?
No repeatability claim is justified by one run. The output provides a fairly complete sequence of visual motifs, but the action and transition differences remain visible. It can be catalogued as a footwear concept prompt tested once; it should not be labelled stable, product-accurate or ready for unrestricted client delivery.
The collection has no repeated outputs, comparison seeds, validated production costs or success-rate denominator. No additional paid generation was needed to document this run. If future tests are made, keep all results and identify changed conditions so a selected attractive sample does not stand in for reliability.
The result also does not prove a general advantage of one model or access method. Token360 identifies the platform used for this request. The source repository’s broader model claims and vendor comparisons are not findings from this single test.
Frequently asked questions
Was this assembled from separate clips?
No. The supplied result is one model-generated sequence without an external edit joining shots. The review images are samples of that file.
Why is there no audio?
The request set generate_audio to false, and metadata confirms no audio track. Silence is part of the tested setup, not an audio-generation failure.
Which seed and fps did you request?
Neither field was sent. The file’s measured average frame rate is 24 fps; that is an observed output property, not a supplied parameter.
Did the model accurately preserve a real boot design?
That was not established. No product reference was supplied, and exact seams, sole details and all-frame consistency were not verified.
Can the complete prompt be republished?
The applicable license remains unverified. The source has an MIT badge, but the linked license file was unavailable. The complete text remains in local editorial records; public reuse needs that permission question resolved.
Where did the prompt come from?
The supplied prompt is attributed to “Retro Suede Boots Brand Concept Film” in Anil-matcha’s awesome-seedance-2.5-api-prompts repository. Its README displays an MIT badge, while the linked license file returned 404 during the November 5, 2026 check. This discrepancy is not treated as verified permission.
The original supplied text was used without action edits. Source attribution and input preservation explain provenance; they do not imply repository endorsement, original Token360 authorship or validation of the repository’s wider model claims.
Playback files are web encodes of the supplied originals, with no editorial cuts. The reported hashes, frame samples and source-track measurements refer to the original files retained in the editorial archive. Compression can alter fine image and audio details; the original files were not replaced.
AI Video
Prompt Library
Case Study
Build faster with one AI API.
Use Token360 to call video, image, audio, and text models with one key and one bill.


 Prompt Library
 Insights
 Insights