Long-Context AI Models: When Is a Larger Window Worth the Cost?
Are long-context AI models worth the cost? Compare capacity, retrieval, and reasoning with research context, a token-volume example, and task-based evaluation.
A larger context window is valuable when it improves the task enough to justify the full workflow cost. The ability to accept more material is a capacity specification. Whether a model finds, combines, and correctly uses that material is a separate question.
Product teams should therefore evaluate long-context AI models around the work users need done. Comparing documents, locating one fact, and maintaining an agent’s working state place different demands on the system. A single maximum-token number does not settle all three decisions.
This analysis was checked November 1, 2026. Research findings below retain their model and task boundaries. The token-volume example and evaluation design are editorial proposals, not Token360 benchmarks, current model prices, or measured customer savings.
Capacity, retrieval, and reasoning are different capabilities
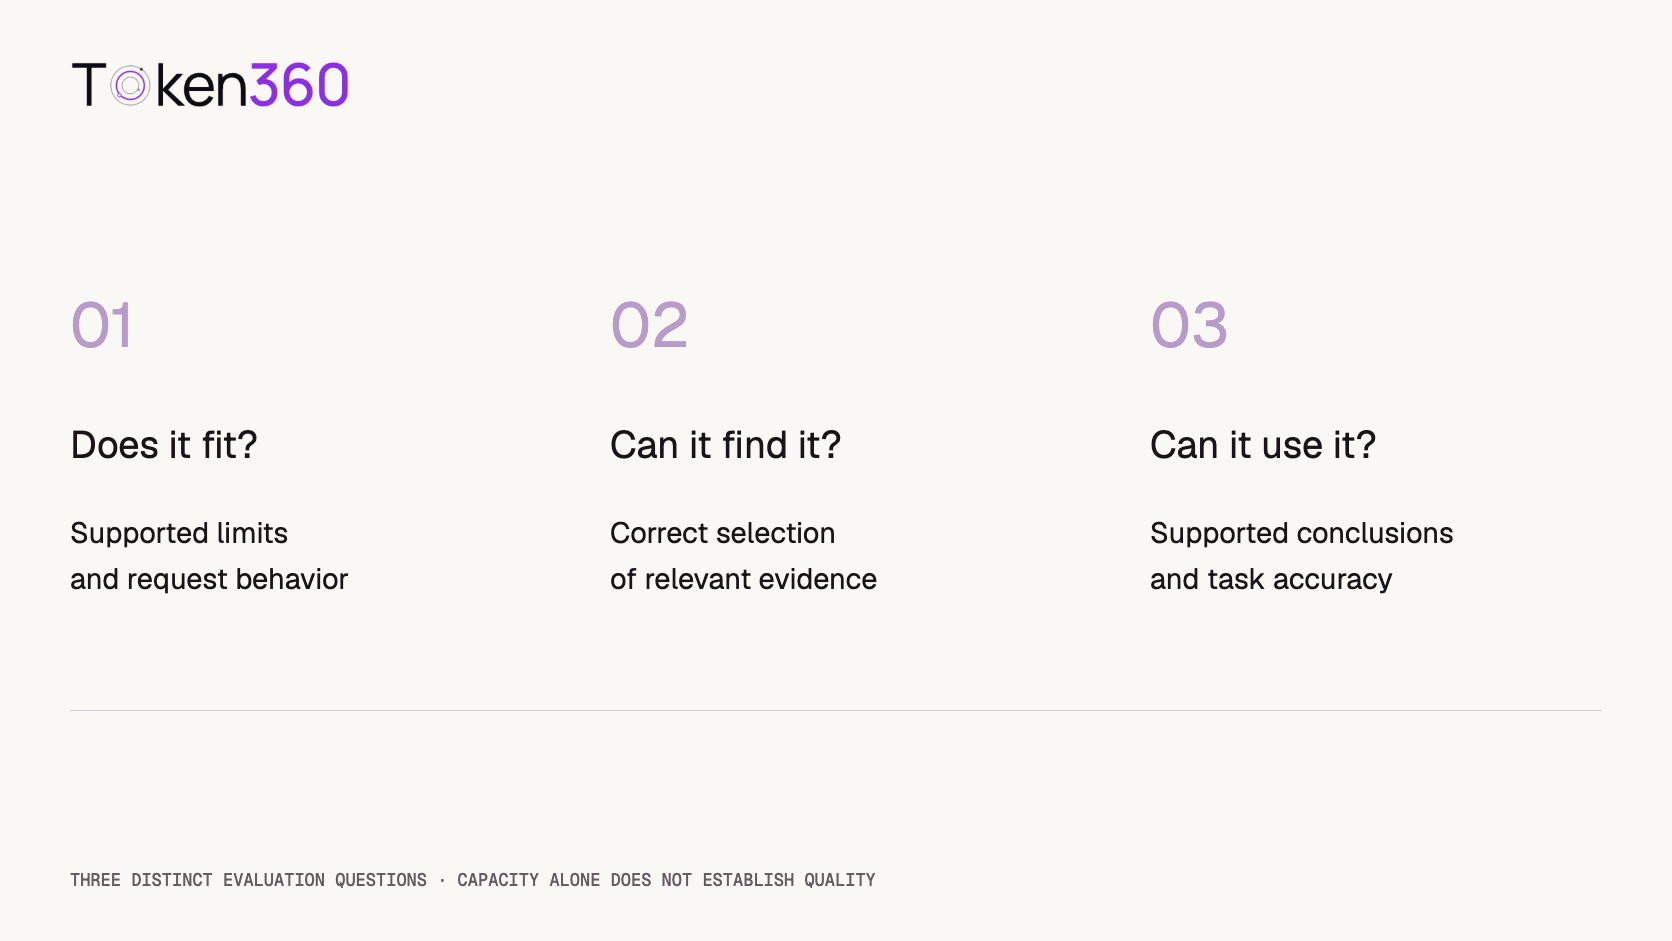
Start with three questions. Can the request fit within the model’s supported limits? Can the model locate the relevant evidence? Can it use that evidence to produce the required answer? A positive answer to one does not establish the next.
Question
Example
Evidence to collect
Capacity
Can the selected route accept the document set?
Supported limits and actual request behavior
Retrieval
Can it identify the applicable paragraph?
Correct evidence selection across representative cases
Reasoning
Can it reconcile two conflicting versions?
Correct conclusions grounded in the relevant passages
A document assistant might retrieve the right sentence but miss an exception elsewhere. A summary might sound fluent while omitting a critical change. Those are task failures even when the API accepts the input and the output contains a citation.
Also check how the selected model accounts for input, output, and any other context-consuming components. Leave room for the actual task instructions and response. Do not assume a headline window size describes the usable document capacity of every endpoint or configuration.
Research argues for testing, not a universal verdict
The 2023 paper Lost in the Middle evaluated multi-document question answering and key-value retrieval. In its tested settings, performance often depended on where relevant information appeared, with weaker results for information in the middle. It is historical evidence about those experiments, not a measurement of every current model.
A later study, Retrieval Quality at Context Limit, reports a different result for simple factoid questions with Gemini 2.5 Flash: accurate retrieval across document positions, including near the input limit. That finding should not be expanded into a guarantee about complex synthesis, every model, or an application’s private documents.
Together, these sources support a practical conclusion: test the task, model, input length, and evidence placement you intend to use. Neither “long context always fails” nor “the window is large enough, so it works” is a sound product-selection rule.
More context can remove one bottleneck and create another
A larger window can let a team compare related documents without first compressing them into a short summary. That can preserve details whose relevance is difficult to predict in advance. It can also simplify an early prototype when document selection would otherwise require a separate system.
But the input still needs curation. Old drafts, duplicated passages, irrelevant logs, and conflicting instructions can add processing work without helping the answer. The useful objective is sufficient evidence for the task, not maximum occupancy of the context window.
Anthropic’s context-engineering article describes managing the information available during inference, including tool outputs and conversation history. Its relevance here is the broader scope of context: the document is only one part of what an application sends.
Three distinct questions. Passing the first does not establish the other two.
Original example: full documents versus selected passages
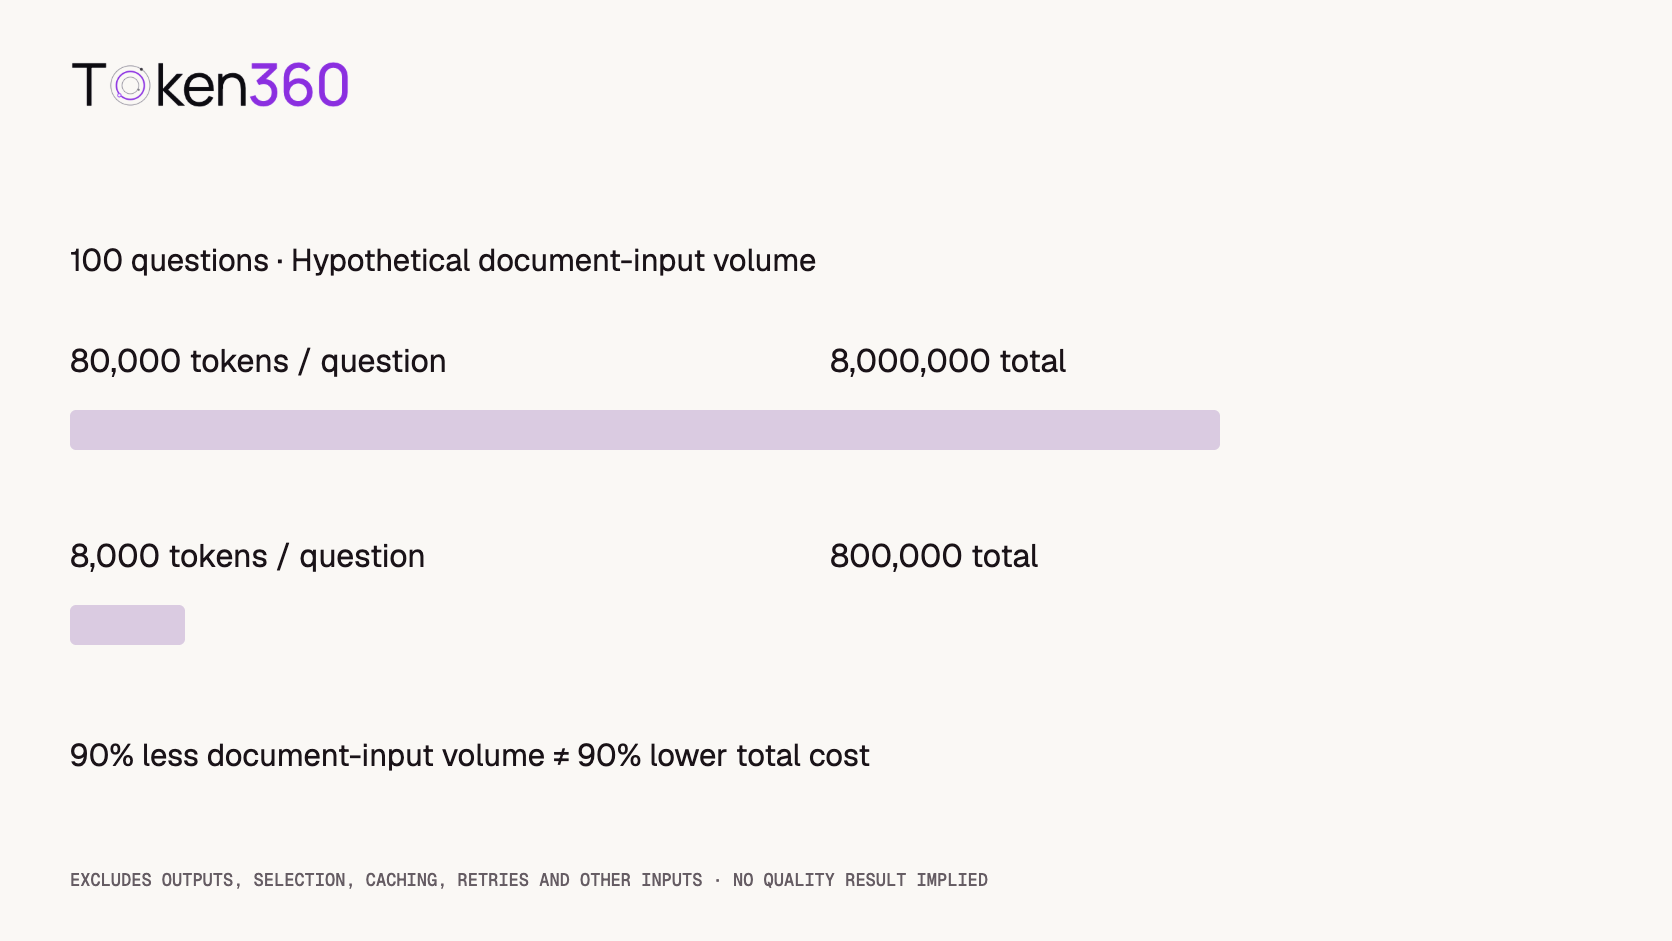
Suppose an application answers 100 questions. In one hypothetical design, every question includes 80,000 document tokens. In another, a selection stage supplies 8,000 document tokens for each question. The first sends 8 million document-input tokens; the second sends 800,000.
Hypothetical design
Document tokens per question
Questions
Document-input tokens
Full-document input
80,000
100
8,000,000
Selected passages
8,000
100
800,000
The selected-passage design sends 90% fewer document-input tokens under these assumptions. This is not a 90% cost-saving claim. The arithmetic excludes system instructions, outputs, selection work, retries, caching, and any pricing differences. It also assumes the selected passages contain the evidence needed to answer correctly.
A selector that misses the decisive paragraph may reduce token volume while making the product worse. A full-document approach that performs well enough with a simpler architecture may be worth its larger input. The comparison needs quality and end-to-end measurements, not token counts alone.
Original arithmetic: 90% less document-input volume, with no inferred quality or total-cost result.
Long context and retrieval can be complementary
A product does not have to choose between sending everything and retrieving only a tiny fragment. It might select several relevant documents, then use a larger window to compare them in detail. Another workflow may retrieve a starting passage and expand to surrounding sections when needed.
These designs distribute responsibility differently. Selection determines what becomes visible to the model. Generation determines what the model does with the available evidence. When the answer is wrong, inspect both stages rather than assuming that a larger model or a larger window will fix the issue.
For a question that genuinely requires a broad comparison, aggressive selection can remove useful context. For a narrow lookup, a whole archive may be unnecessary. Choose the workflow around the information dependencies of the question, and retain source references so the final answer can be checked.
Test difficult evidence patterns, not just one hidden fact
A simple retrieval check is useful, but it should not be the entire evaluation for a complex product. Include questions requiring more than one passage, documents with similar names, outdated and current versions, and cases where the correct answer is that the supplied material is insufficient.
For example, a support assistant might encounter a current product policy alongside a superseded draft. The test should check whether it uses the applicable version and explains any uncertainty. Finding a phrase that appears in both documents is a weaker task than resolving which statement governs the answer.
Vary evidence placement and input length when these vary in production. Keep the expected answer and supporting passages explicit. If you compare workflows, identify whether each receives the same source set or a selected subset, and report selection failures separately from answer-generation failures.
Use a representative evaluation set rather than interpreting one successful demonstration as reliability. The appropriate number of cases depends on the task and failure consequences; this article does not propose a universal sample threshold.
Measure the cost of an accepted answer
Useful measurements include answer correctness, evidence support, completion time, actual billed usage, and the amount of review or retry work. Define what “accepted” means before comparing candidates. Otherwise, a cheaper response can appear attractive simply because its defects are not counted.
Report latency for the full workflow, including document selection and preprocessing where applicable. Measure repeat requests separately if caching is part of the design. A cold request and a reused context may have different operational characteristics; verify the selected service’s behavior rather than assuming a discount or speedup.
The AI API cost management guide can help organize usage tracking. Treat a model’s maximum context as one input to that decision, alongside quality and the surrounding system’s maintenance effort.
When the larger window earns its place
A larger context window is a strong candidate when the task needs relationships across many passages, important evidence is hard to select in advance, and evaluation shows the model handles the material well enough. Its value may include simpler document handling, not only a higher answer score.
A narrower or selected context is a strong candidate when relevant evidence can be identified reliably and the extra material contributes little. That choice still needs testing: removing surrounding qualifications can damage an otherwise correct answer.
The decision can differ by workload. A single-fact lookup and a multi-document comparison need not share the same input strategy. Keep the routing rule understandable and measure whether the additional complexity is justified by the observed benefit.
Check the actual model route before committing
Use Token360’s model capability documentation and the selected model’s schema to confirm supported inputs and limits. A provider-level capability does not establish identical behavior through every serving route.
Record the model identifier, input construction, output settings, and evaluation date. Use the AI API observability guide to connect operational changes with the workload. This article does not claim a tested Token360 long-context configuration or recommend a particular model as the universal winner.
FAQ
What is a long-context AI model?
It is a model that supports comparatively large inputs within its context limits. The relevant limit and accounting rules depend on the model and route; capacity alone does not establish task accuracy.
Does a larger window mean better answers?
Not automatically. More material can preserve useful evidence, but the model still needs to identify and use it correctly. Evaluate the actual task rather than the maximum-token specification.
Do all models lose information in the middle?
No universal conclusion follows from the cited studies. Results differ across models and tasks, which is why evidence placement belongs in evaluation when it matters to the application.
Does long context replace retrieval?
Not necessarily. Retrieval can select useful documents, while a larger context supports detailed comparison within that set. The appropriate combination depends on quality, cost, and complexity.
Does the 90% example represent savings?
No. It represents a hypothetical reduction in document-input token volume. Actual cost also depends on pricing, caching, outputs, selection work, and retries.
What should I test before choosing a model?
Test representative questions, evidence placement, conflicting versions, multi-passage reasoning, and missing-answer cases. Measure supported answers and full-workflow cost and latency together.


 Comparison
 Tutorial
 Tutorial